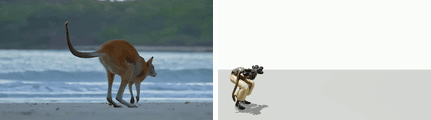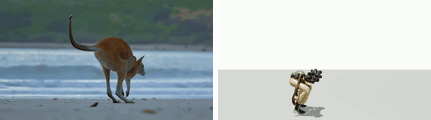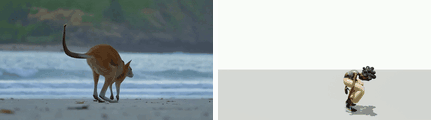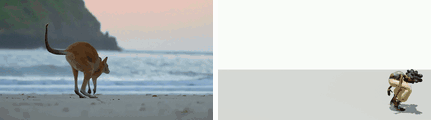
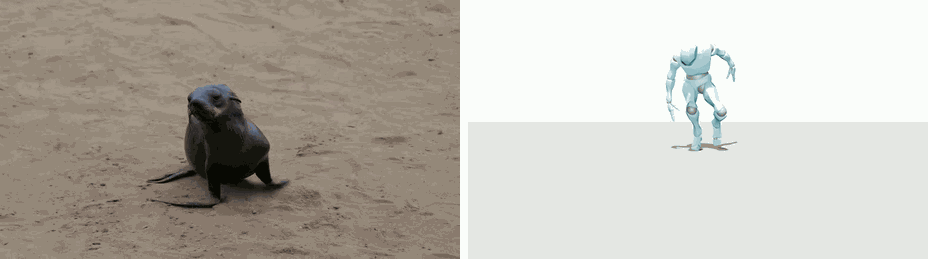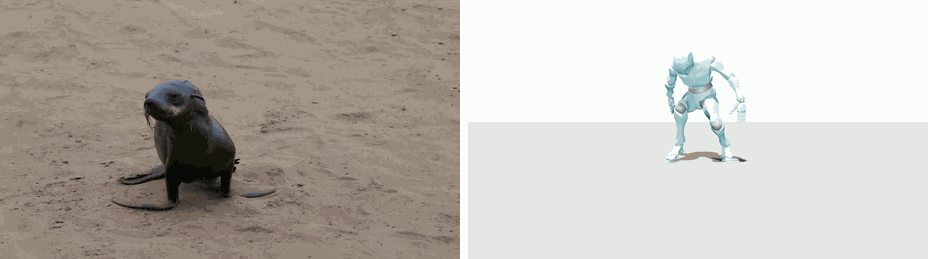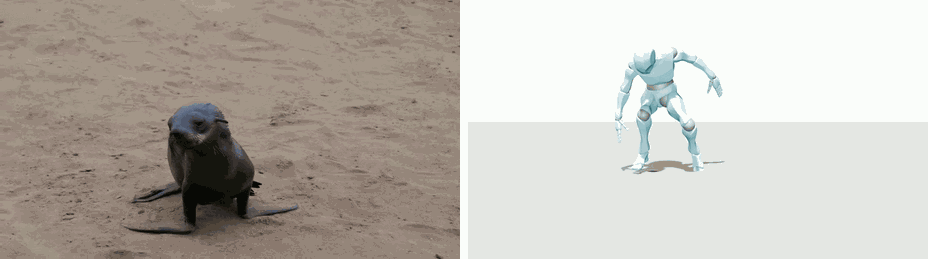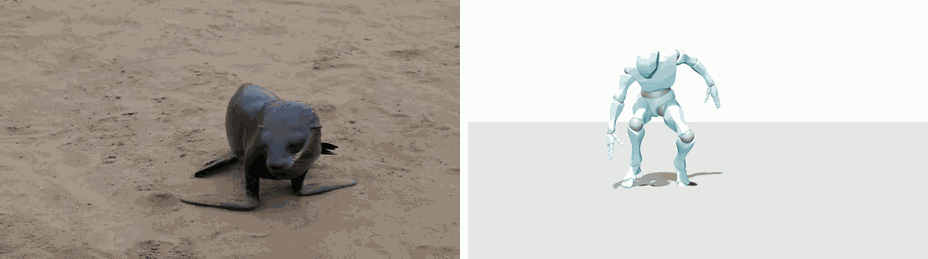
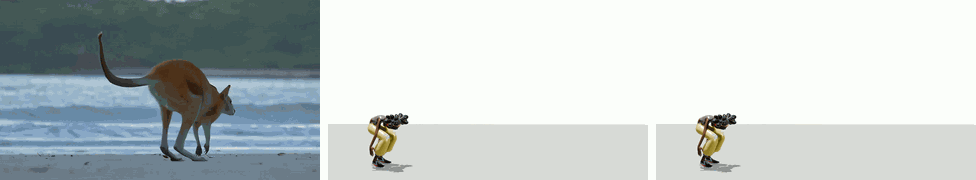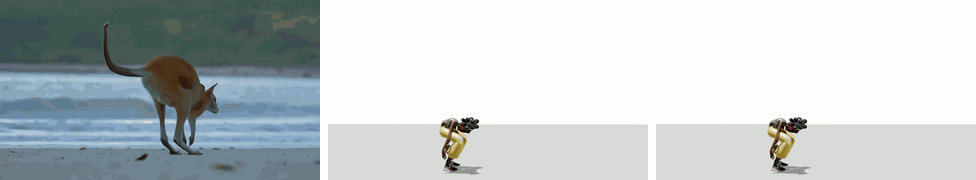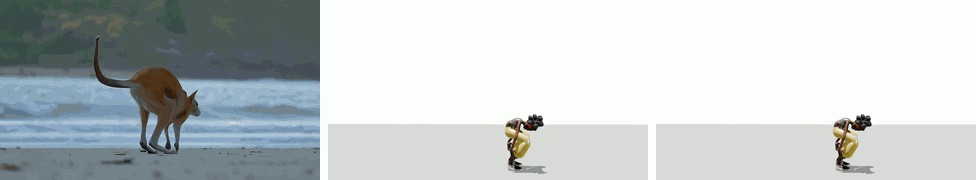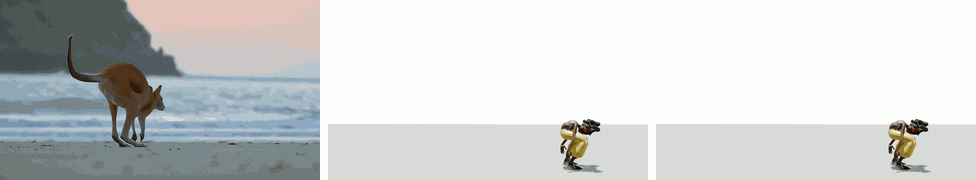
Kangaroo-like jumping
1Peking University 2Nankai University 3The University of Hong Kong 4Zhejiang University 5Pengcheng Laboratory
arXiv 2026
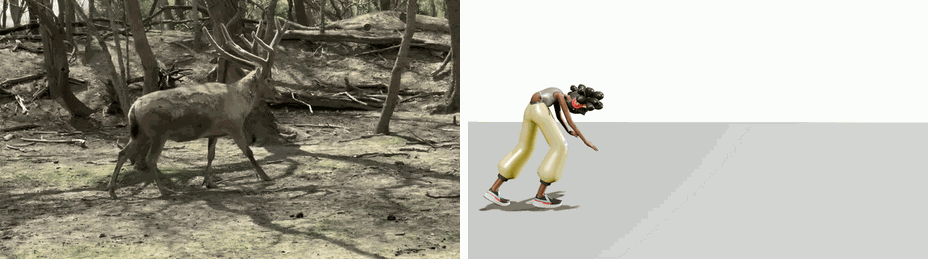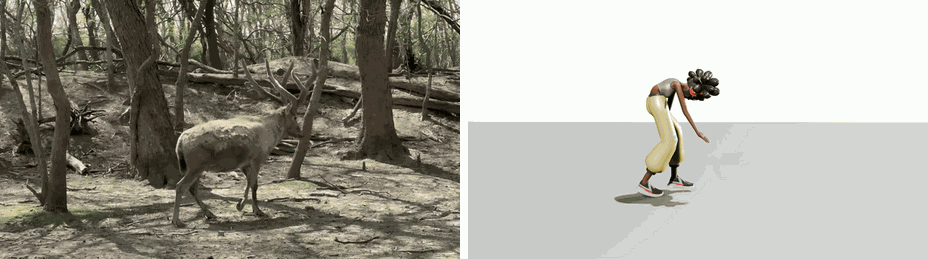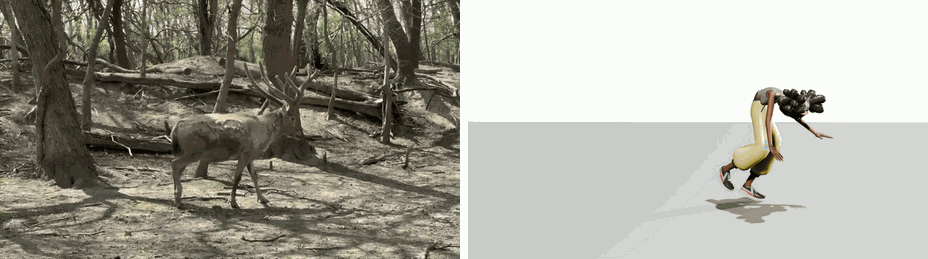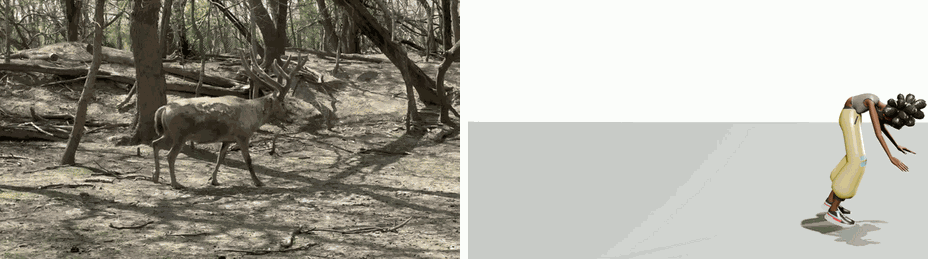
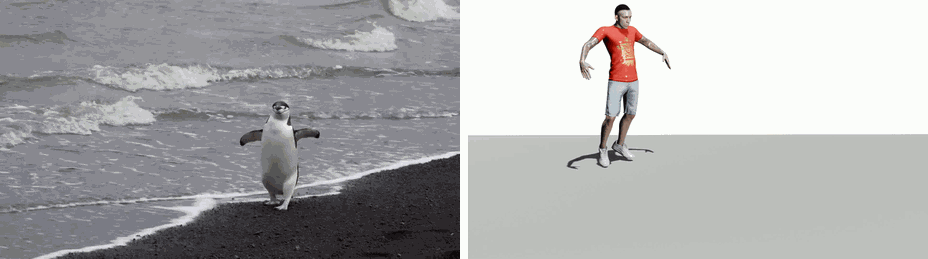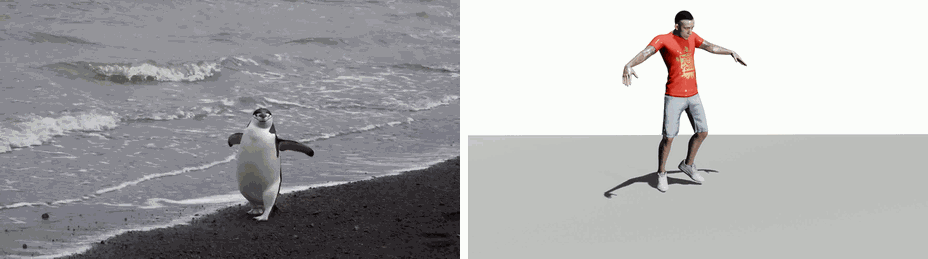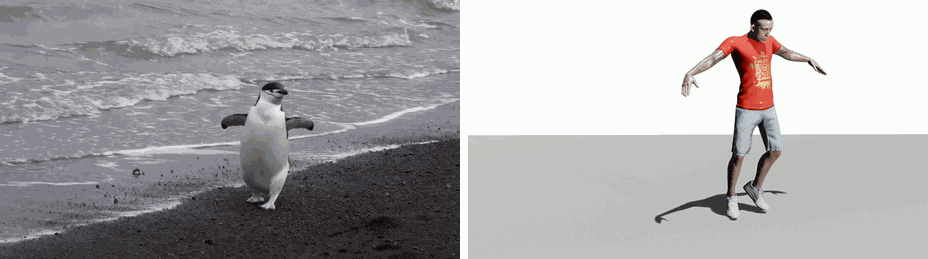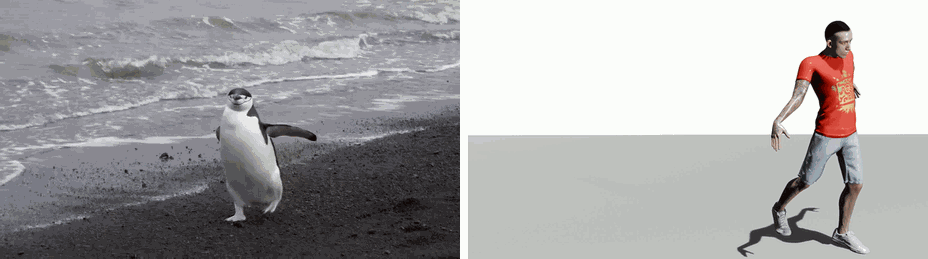
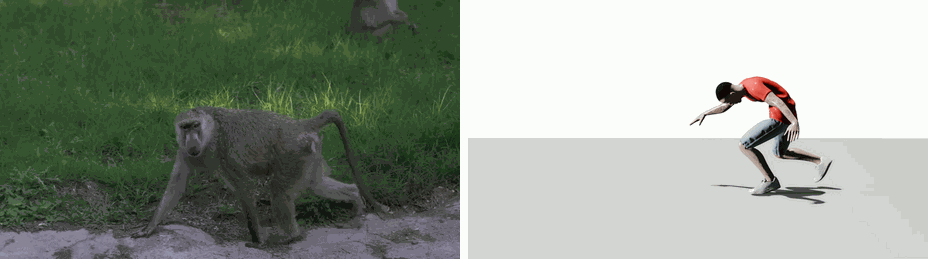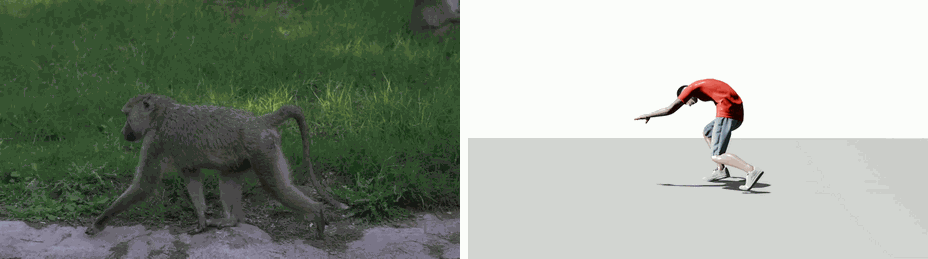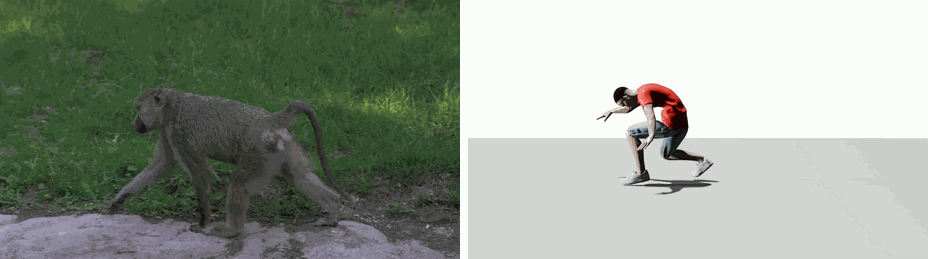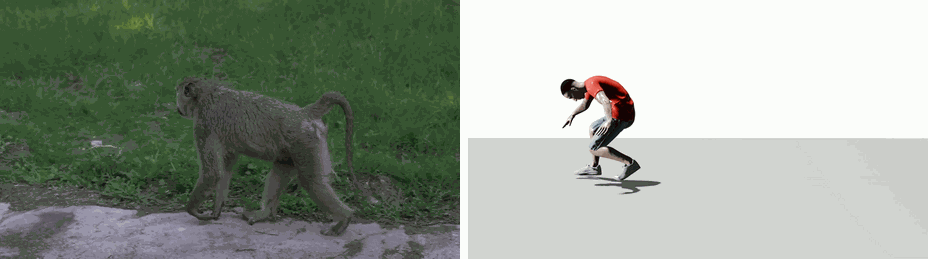
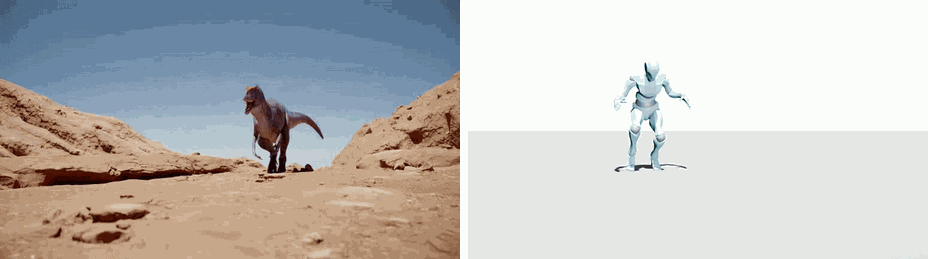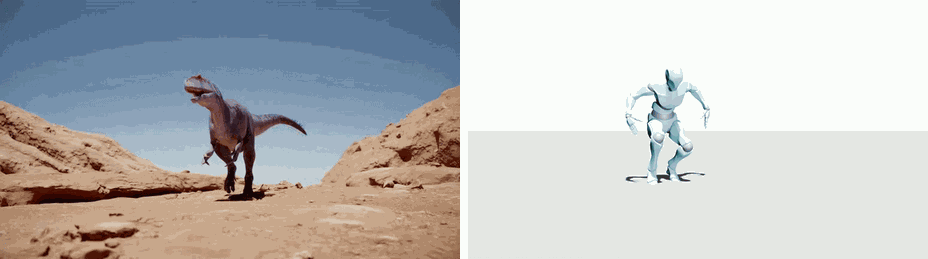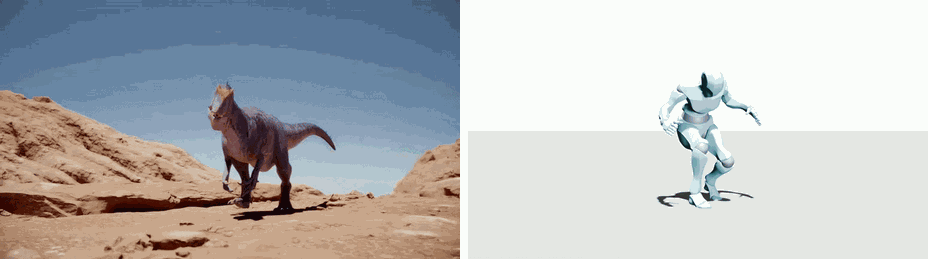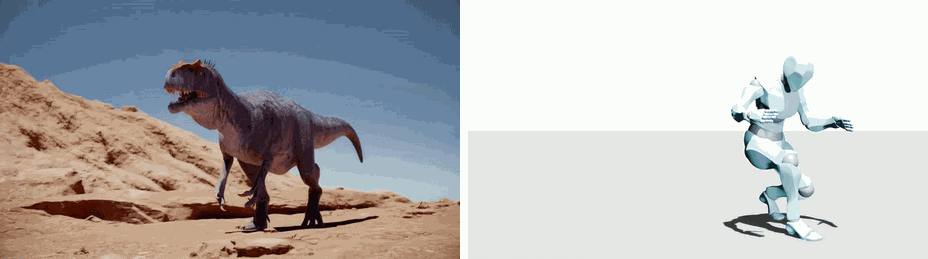
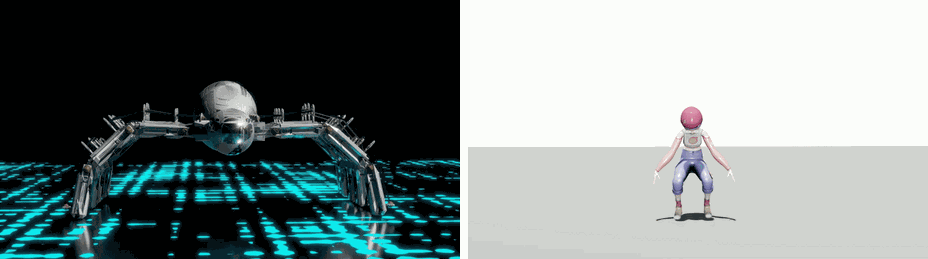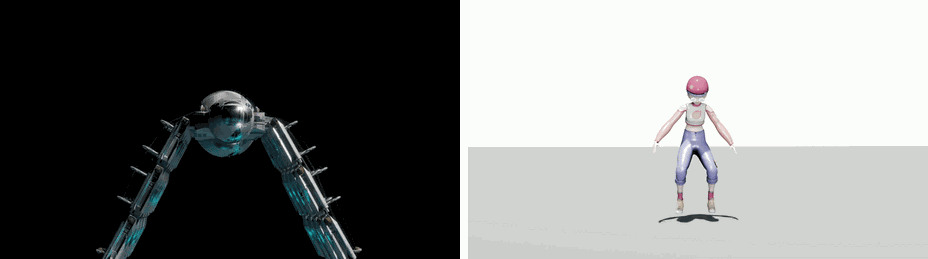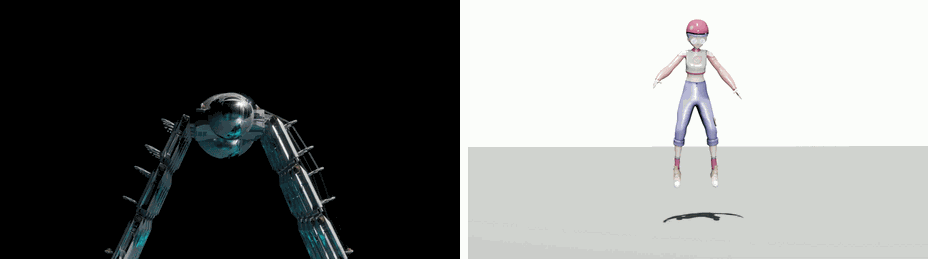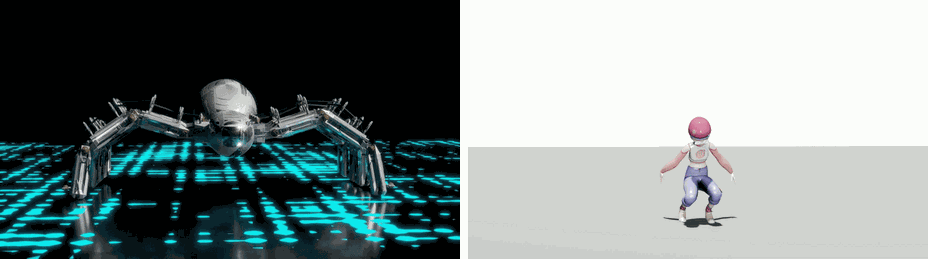
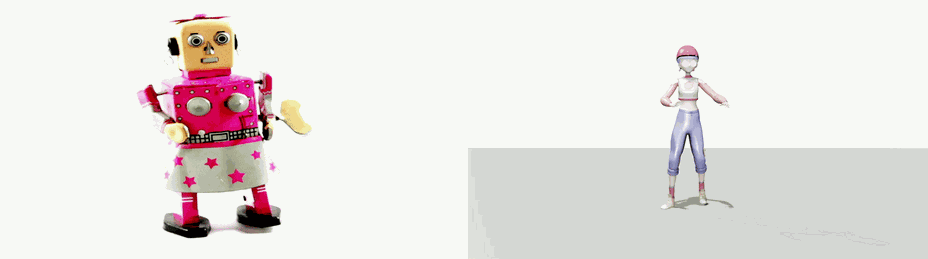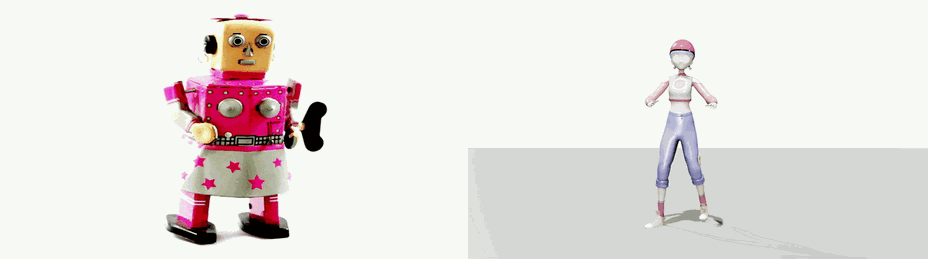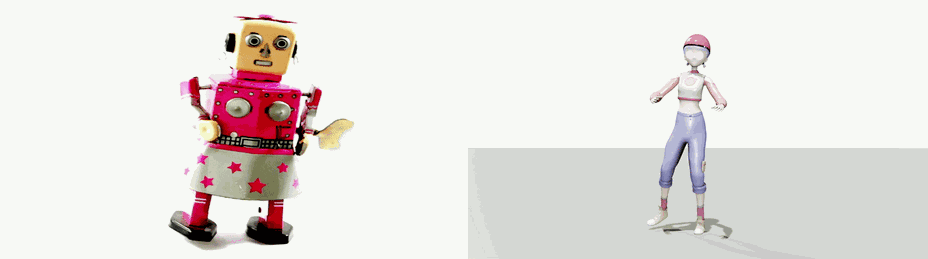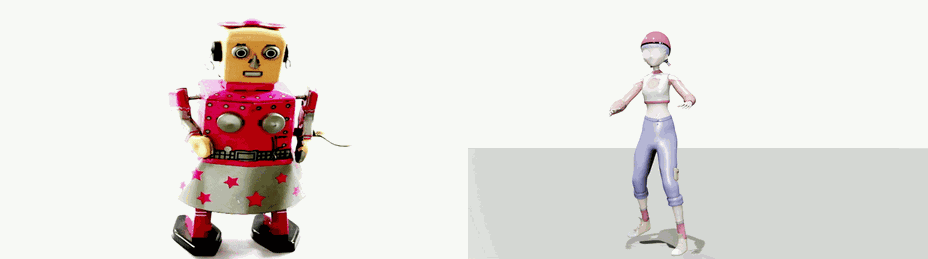
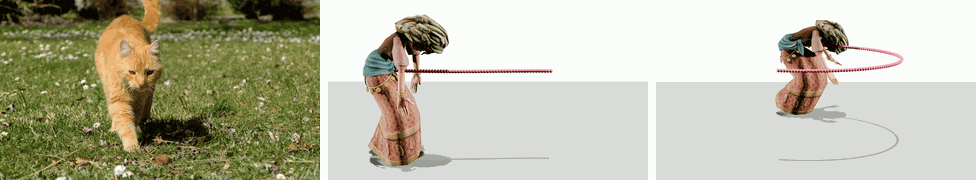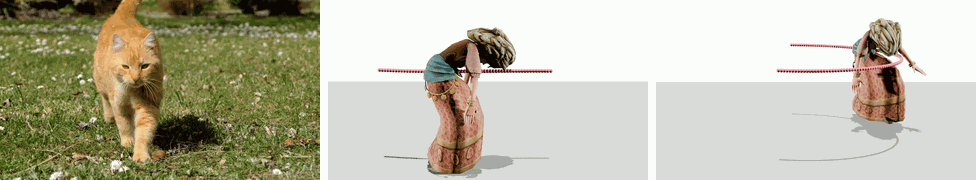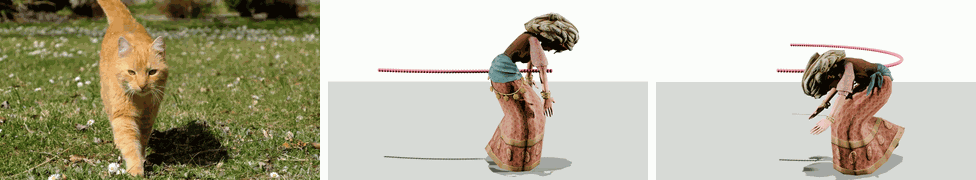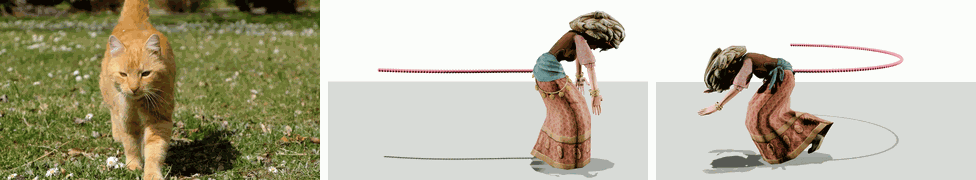
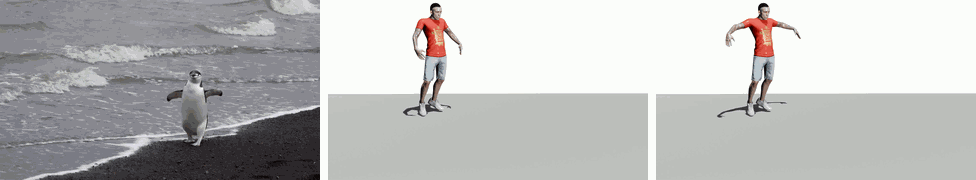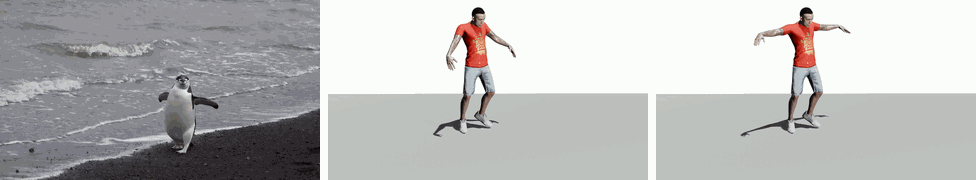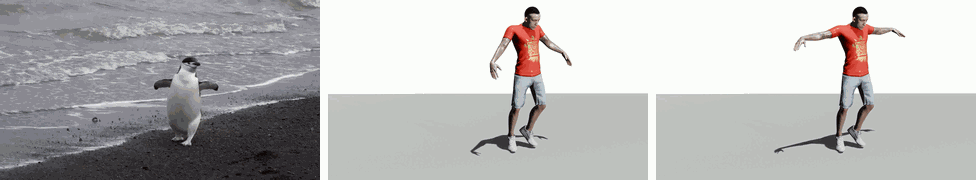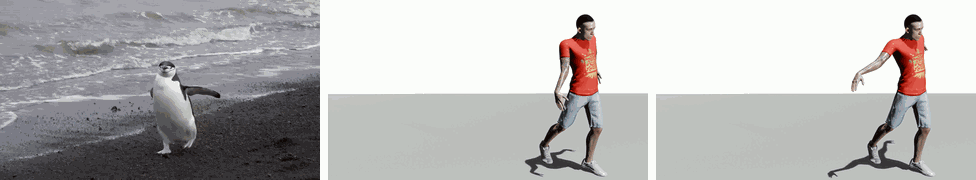
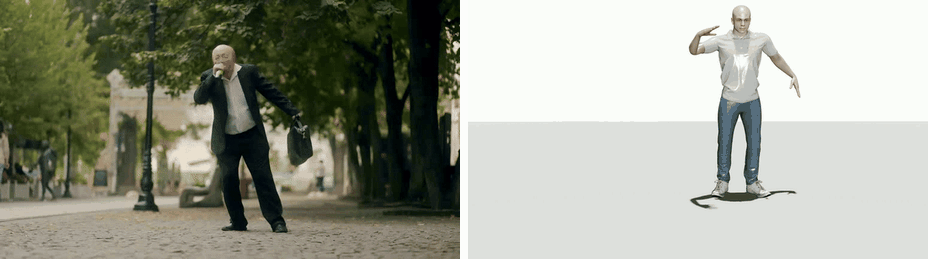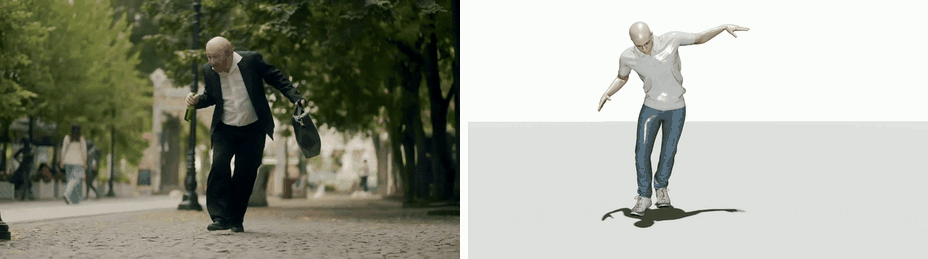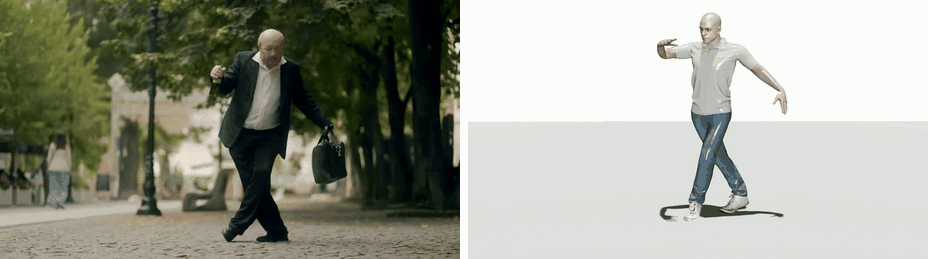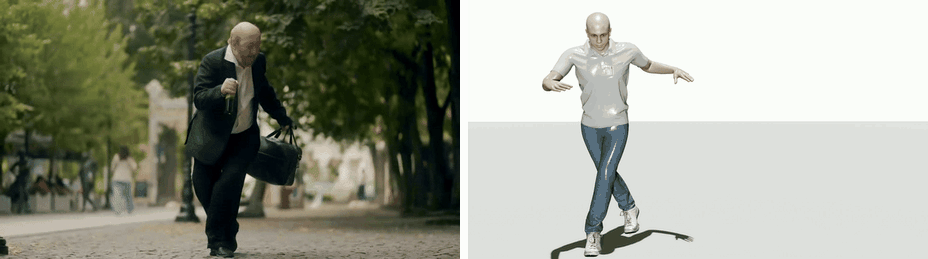
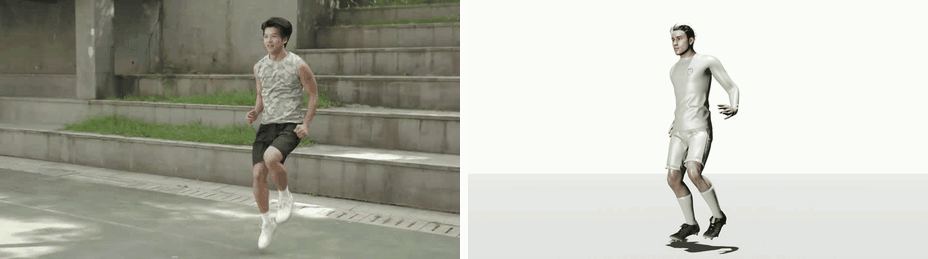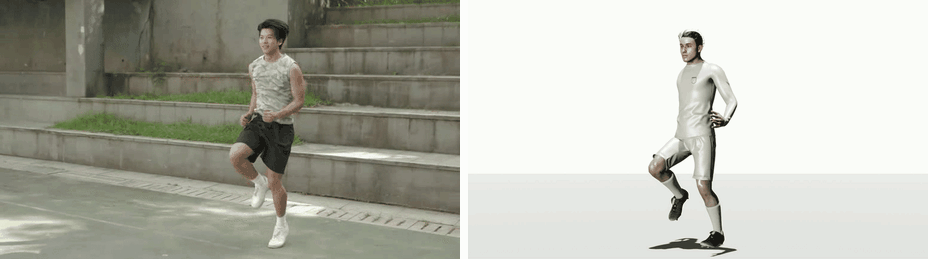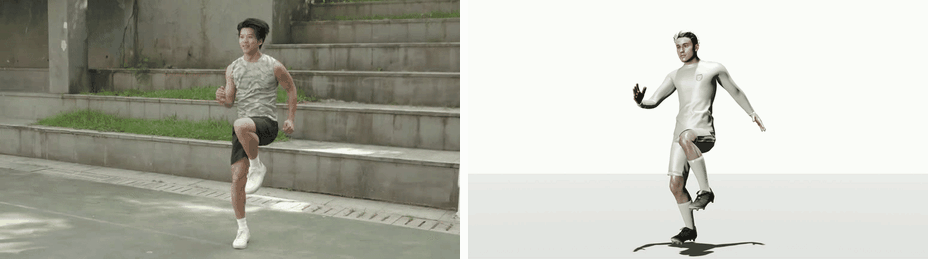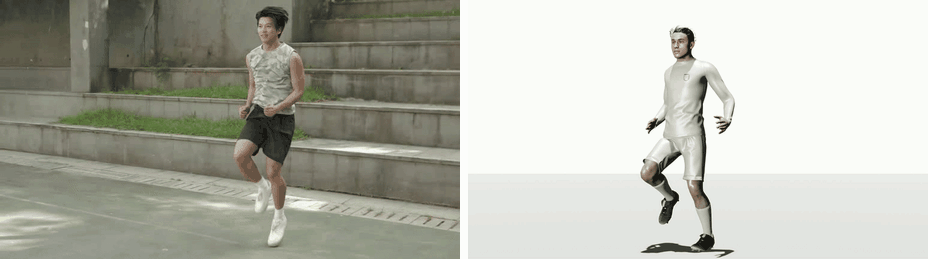
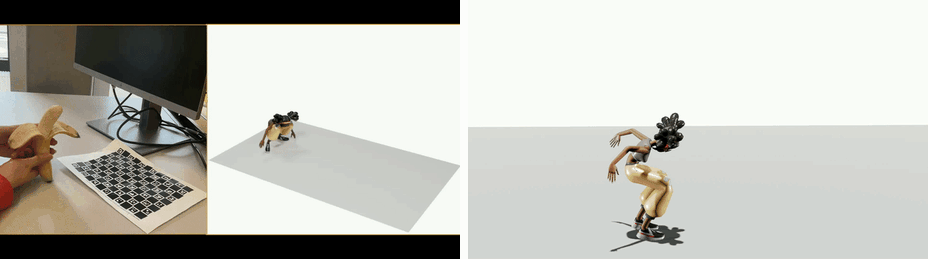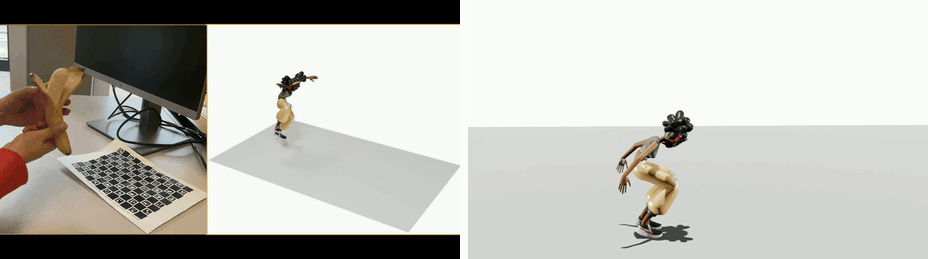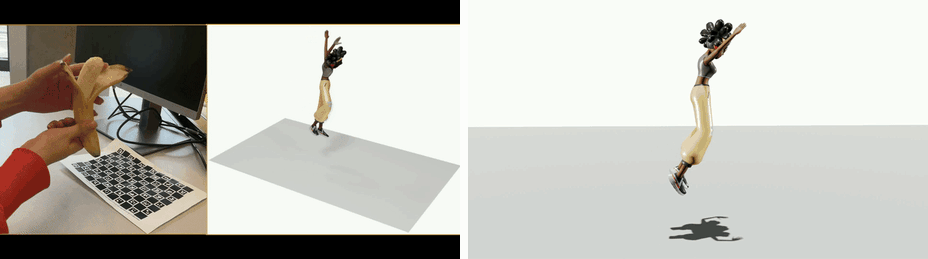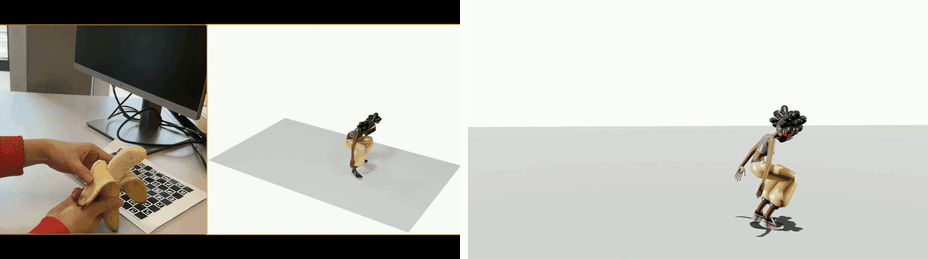
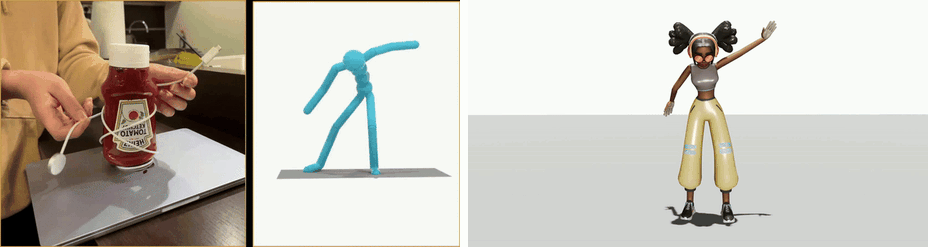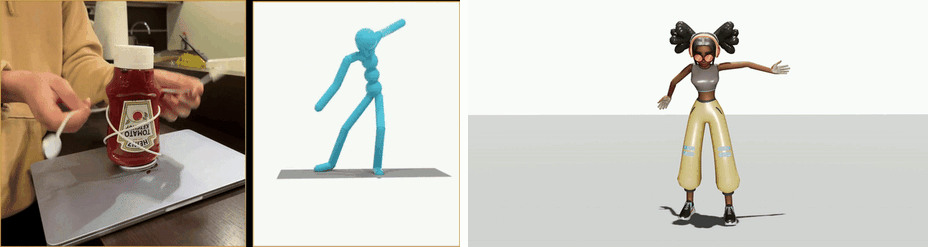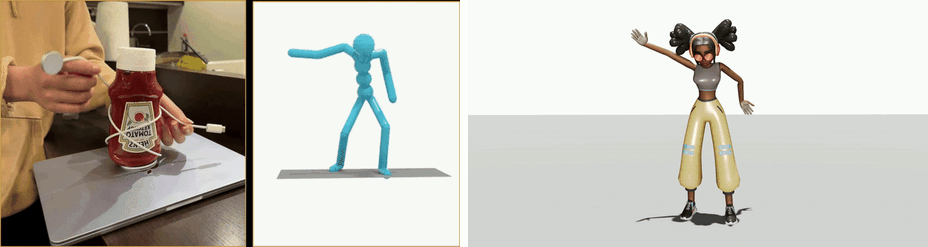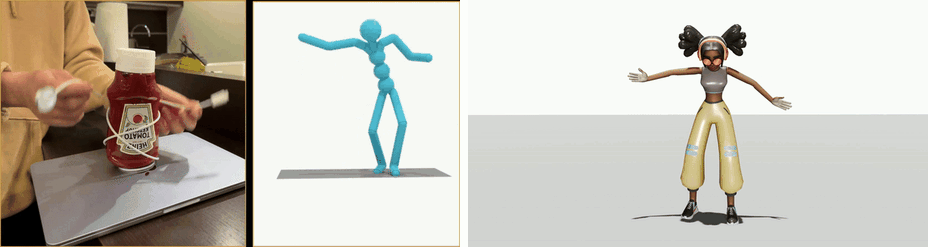
AnyAct reenacts human motion from arbitrary character videos. It converts sparse 2D motion cues from animals, cartoons, objects, and stylized characters into plausible 3D human motions that preserve the source action semantics. Given monocular videos of non-human characters with diverse topologies, AnyAct reinterprets their characteristic motion patterns as plausible human performances rather than reproducing their source structures literally. Shown here are reenactments of (a) kangaroo-like jumping, (b) butterfly-like wing flapping, and (c) beckoning-cat-like waving.
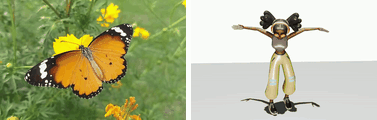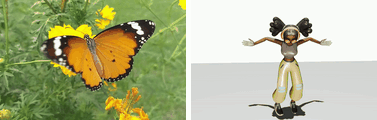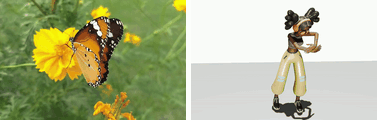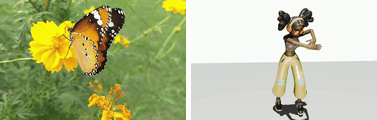
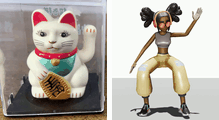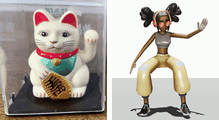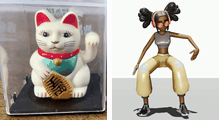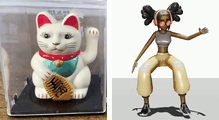
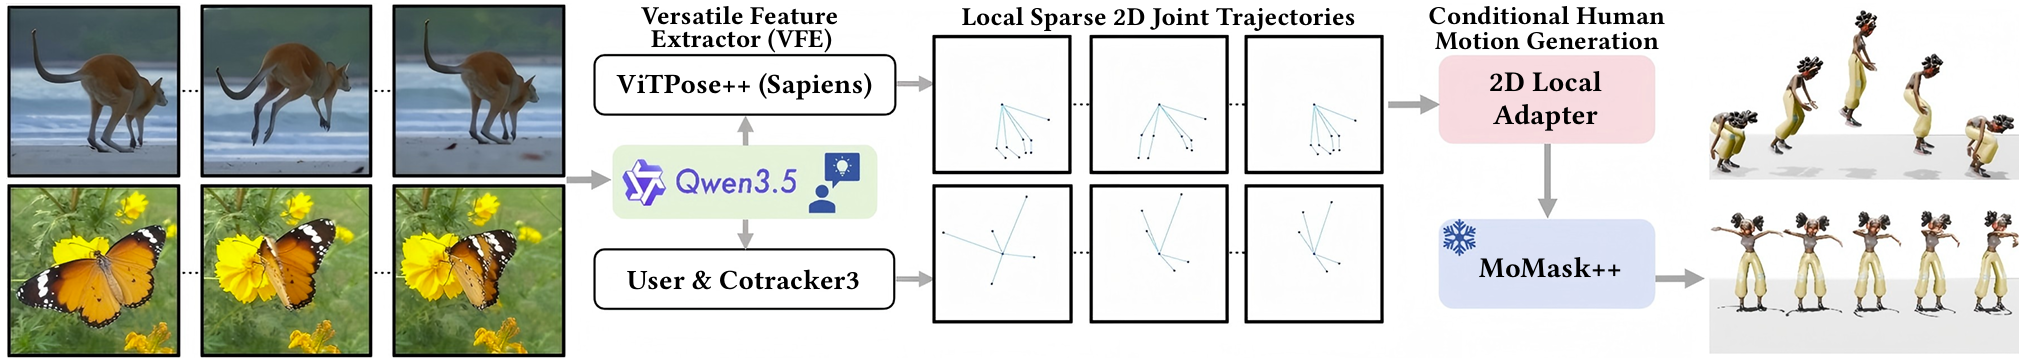
Given reference videos of characters, AnyAct first extracts local sparse 2D joint trajectories as transferable motion cues from the input video using our model-ensemble-based Versatile Feature Extractor (VFE). These cues are then injected into a human motion generator (MoMask++) through the ControlNet-like 2D Local Adapter (2D-LA) to produce the initial human reenactments that follow the observed character dynamics.
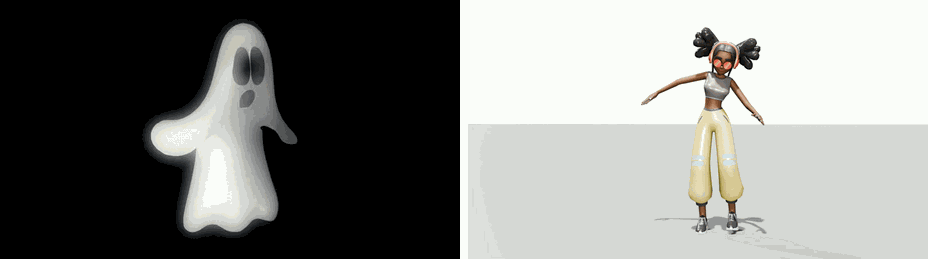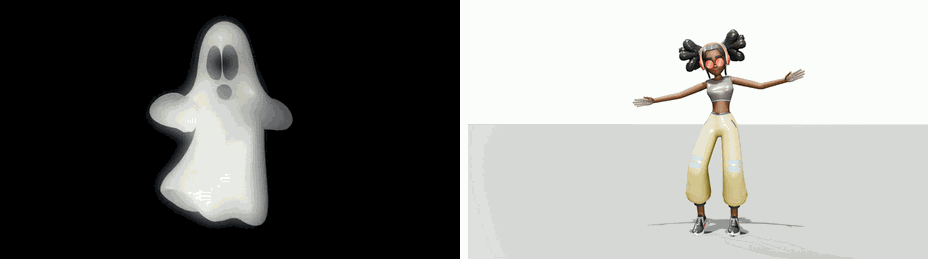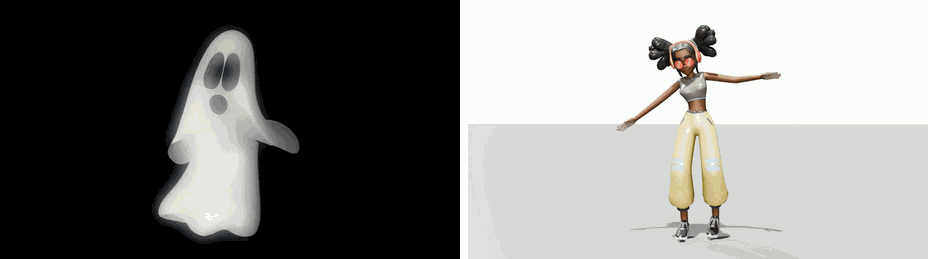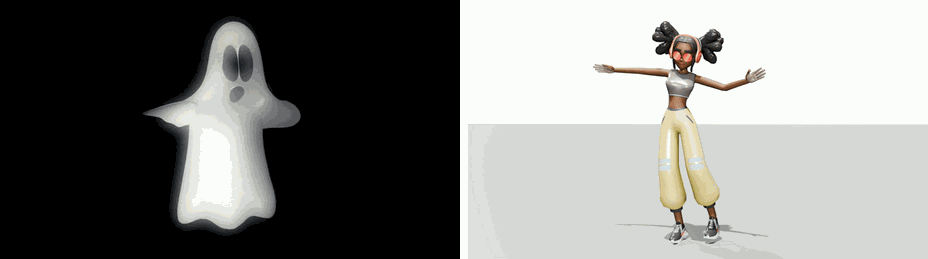
@article{chen2026anyact,
  title={AnyAct: Towards Human Reenactment of Character Motion From Video},
  author={Chen, Liuhan and Zhong, Lei and Wang, Jiewei and Shuai, Qin and Yuan, Li and Fan, Leidong and Li, Qing and Liu, Kanglin},
  journal={arXiv preprint arXiv:2605.15497},
  year={2026}
}